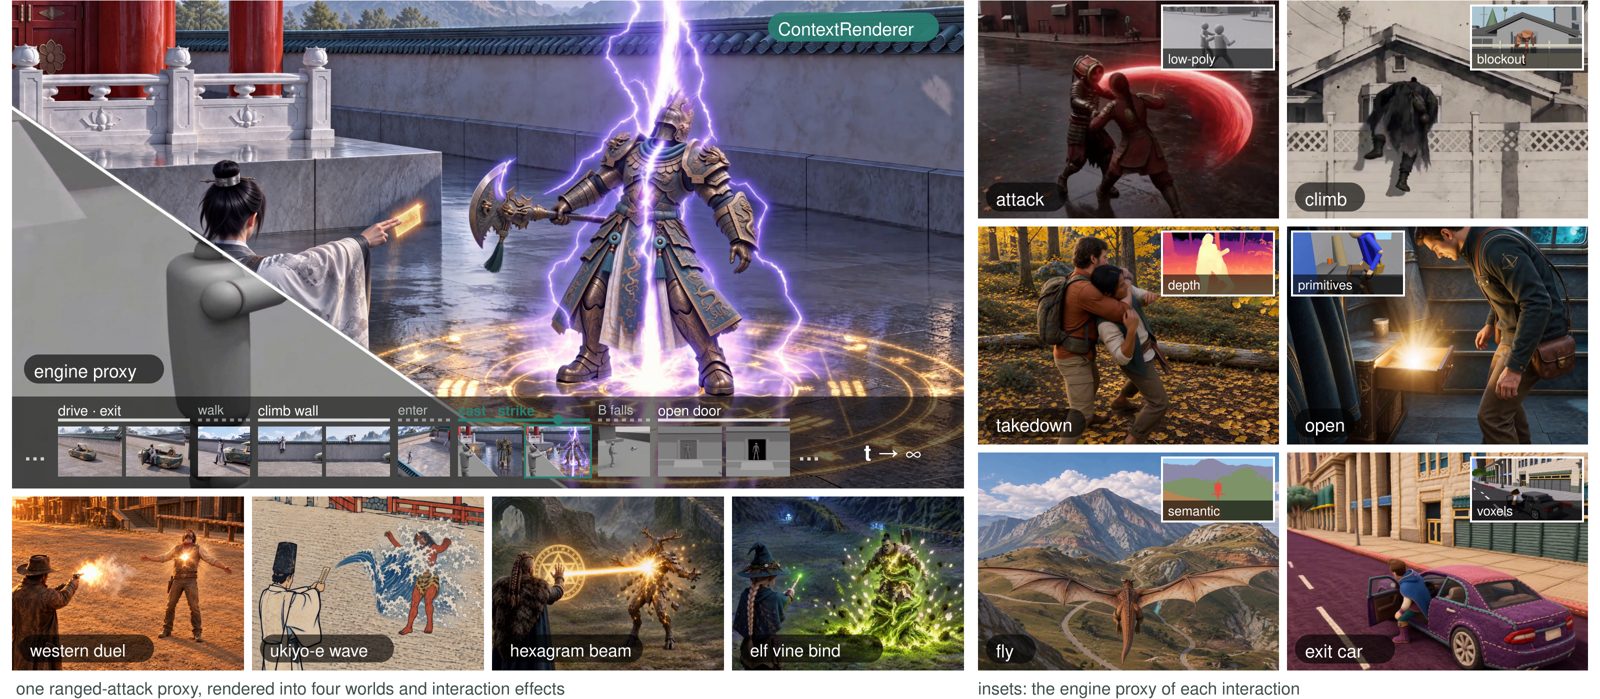
One ranged-attack proxy, rendered into diverse worlds and interaction effects. ContextRenderer generates successive video chunks from refreshed world context and visual history.
Interactive game world models separate executable world evolution from visual generation, using video models to render engine-provided scene representations into detailed observations. During sustained gameplay, however, existing generative renderers struggle to follow changing conditions while preserving visual continuity across diverse proxies and target styles. We therefore introduce ContextRenderer, an autoregressive video diffusion framework designed for both dynamic conditioning and cross-proxy generalization. It couples Dynamic-Context Learning (DCL) for chunk-level interaction supervision with Recurrent History Compression (RHC) to follow condition updates while preserving visual continuity within a bounded token budget. Across proxy representations, Cross-Representation Flow Alignment (CRFA) connects proxy reconstruction with appearance and interaction variation through a shared high-fidelity reconstruction. WorldPrism, our interaction-centric dataset constructed from agent-built worlds, AAA gameplay, and open-source videos, supplies the corresponding renderings and chunk-level annotations for these learning tasks. Experiments on GWM-Bench and Solar-Bench show improved reconstruction and visual quality, while qualitative results demonstrate minute-long interactive rendering under changing prompts and subject references.
@article{wang2026contextrenderer,
  title={ContextRenderer: Dynamic-Context Video Generation for Interactive Game Worlds},
  author={Wang, Runze and Zha, Fei and He, Bing and Xu, Ke and Wu, Zhongyuan and Xie, Yuxuan and Wu, Wenzheng and Liu, Zhongyuan and Cai, Youcheng and Liu, Ligang},
  year={2026}
}